Let your
agents run.
Qwen3.8 Flash for the tools you already code with. Flat monthly pricing. No bill for every token.
No card required. Resets Monday at 00:00 UTC.
Need more room? Paid plans from $19/month.
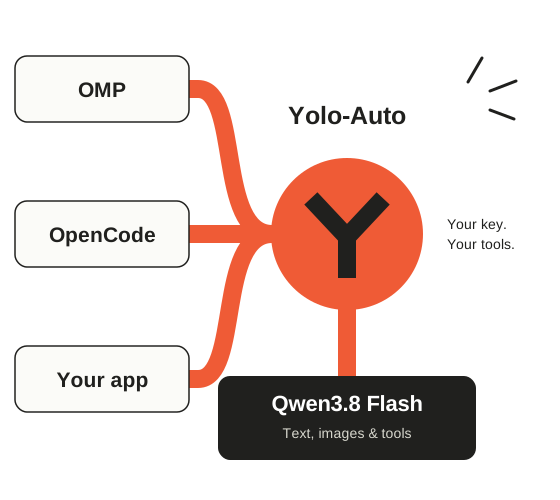
- OMP
- OpenClaw
- Hermes
- OpenCode
- Cline
- OpenAI SDK
- 180.8Btokens served
- 3.9Mrequests handled
Independent benchmarks · Artificial Analysis
Same score.
Flat-rate access.
Qwen3.8-Flash-Next matches DeepSeek V4.1 Flash on the published Intelligence Index: 40 points each. Compare it with DeepSeek, GPT-5.6 Luna, and GLM-5.3 Flash below.
Intelligence Index
Version 4.3 · Index points
- Qwen3.8-Flash-Next
- 40
- GPT-5.6 Luna (max)
- 38
- GLM-5.3-Flash
- 42
- DeepSeek V4.1 Flash (max)
- 40
AA-Briefcase
Agentic knowledge work · Elo
- Qwen3.8-Flash-Next
- 1587
- GPT-5.6 Luna (max)
- 1333
- GLM-5.3-Flash
- 1449
- DeepSeek V4.1 Flash (max)
- 1424
Terminal-Bench 4.0
Terminal tasks · Percent score
- Qwen3.8-Flash-Next
- 25%
- GPT-5.6 Luna (max)
- 12%
- GLM-5.3-Flash
- 33%
- DeepSeek V4.1 Flash (max)
- 27%
Charts by Yolo-Auto using published scores from Artificial Analysis, checked September 15, 2026. Published rounded scores; reasoning models, with GPT and DeepSeek at Max Effort. Selected benchmarks, not a claim of equal performance on every task. Methodology.
These are Artificial Analysis model results, not a benchmark of the Yolo-Auto endpoint.
Flat-rate.
By design.
Start free. Add capacity when you need it.
Paid subscriptions renew monthly. No token credits, no per-token overages. Cancel anytime.
Compare limits and estimated costsFree
Prove Yolo-Auto works in your stack before you pay.
- 15 requests/week, resets Mondays at 00:00 UTC
- Qwen3.8 Flash
- 128K context for real prompts and docs
- No card required, free forever
Builder
Best valueFor coding agents and daily development.
- No per-token billing
- 128K context for repositories and long conversations
- Approximately 200 million tokens a day
- Up to 5x concurrency
- Cancel anytime
Pro
For heavier interactive workloads that need more context and headroom.
- Everything in Builder
- 256K context for larger repositories
- Approximately 750 million tokens a day
- Up to 10x concurrency
- Cancel anytime
Know where
your work goes.
Your work is not training data.
We process requests to generate responses, not to train models. Prompt and response bodies are not stored or retained.
We keep operational metadata such as model, token counts, status, and latency to run the service.
Read the privacy policyReal infrastructure. Reachable people.
We operate a focused model-serving stack on dedicated capacity, with Cloudflare and other service providers supporting networking and operations.
Need help? Email hello@yolo-auto.com. You don’t need to join a Discord server to ask a question.
About Yolo-AutoGo build.
Start with 15 free requests a week.
Bring a task you actually want to finish.